In brief
‘Token factory’ is a figure of speech for a system or platform that produces AI output at scale. The term is used in the context of AI factories and inference infrastructure. It is not a distinct type of language model, nor is it a universal technical standard. This article concerns tokens from AI models, not the creation of crypto tokens.
What does such an environment consist of?
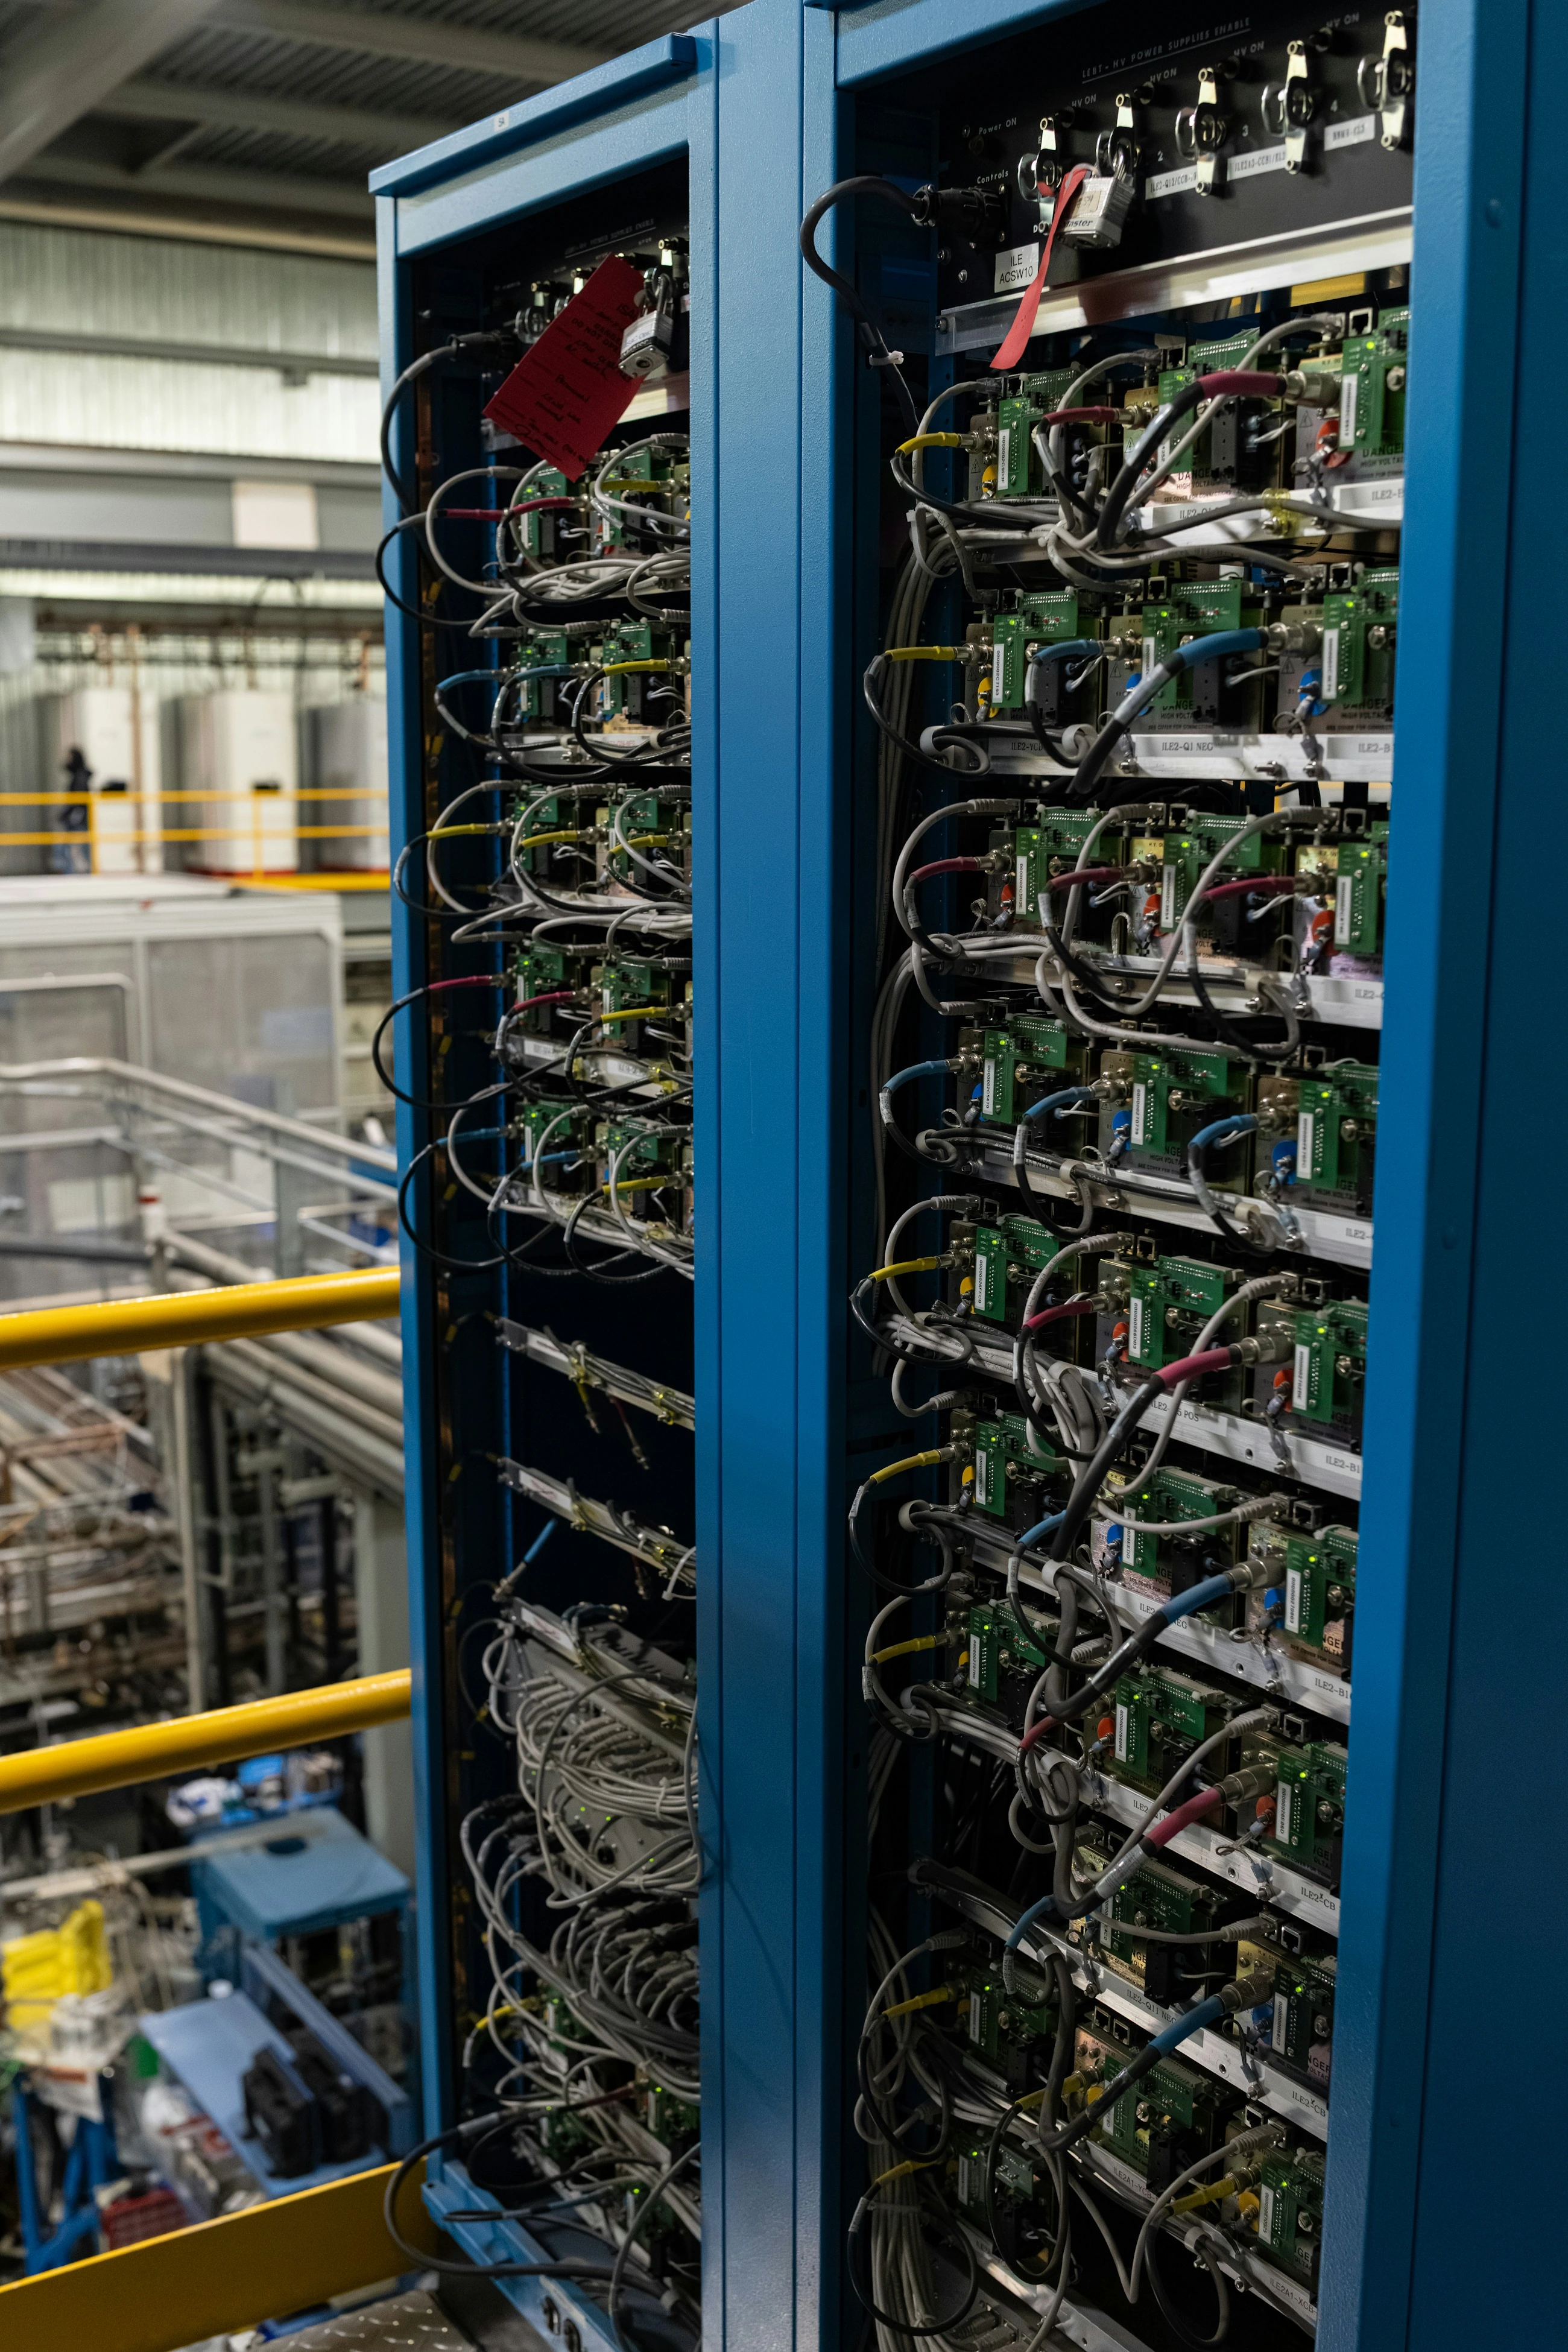
Models, computing hardware, memory, networks and software are required to process requests. This is supported by, amongst other things, data provision, access management and monitoring. NVIDIA uses AI Factory for a broader infrastructure that can also support training and other AI activities. Token Factory focuses primarily on the production of model output during operation.
Why is it called a factory?
The analogy illustrates a chain: data and commands are received, calculations are performed, and usable output is sent to applications. Just as in a production process, there is capacity, queues and quality control. However, the word ‘factory’ says nothing about the quality of each response. More tokens produced can also mean more redundant text.
A practical example
An organisation allows multiple internal applications to use the same model server. An assistant asks questions, a document workflow generates summaries and a developer has code explained. The platform allocates capacity and records usage. Even on a small scale, this can already constitute a shared AI facility; the term ‘factory’ does not automatically imply a large data centre.
How do you assess capacity and costs?
Tokens per second can be useful, but do not indicate how many users receive a satisfactory result within the desired time. Also measure waiting time, utilisation and successful tasks. A machine that is left running all day for a few short queries may prove more cost-effective than the same machine with a constant workload. Electricity, purchase and management costs should therefore be included in the comparison.
What suits ‘AITJE’?
Start with the tasks and the expected usage. For some organisations, a dedicated shared model server is suitable; for others, an API or a combination of both. Configure the input efficiently and route different tasks to suitable models. The aim is to achieve usable AI capacity with insight into usage and costs, not to generate as many tokens as possible for the sake of it.
From concept to practice
How AITJE applies this
For organisations with multiple AI workflows, we assess whether shared model capacity is appropriate. We analyse usage, capacity and costs per task and determine which processes should be carried out locally or externally. Code, targeted context and model routing can help minimise the necessary computational workload. The term ‘token factory’ does not refer to a separate ‘AITJE’ product in this context; it refers to the appropriate configuration of AI processing.
Token management & optimisationFrom explanation to application
Would you like to know what this means for your work?